- Measured, not guessed: 11 timed runs across 10, 50 and 214-page text files plus a 30-page image scan.
- Exact controls: 9-point grid, point offsets, outline stroke, tile spacing in points, page-range syntax, placeholders.
- Opacity lab: rendered contrast at 8, 15, 25, 35 and 50 percent on white, dark, form and photo pages.
- Honest limits: the three ways a watermark gets removed, what breaks a digital signature, why Hindi text turns into boxes.
- 12 recipes: contracts, invoices, portfolios, ebooks, exhibits, course notes, client proofs and more, with every field value.
- Per-recipient marking: a four-layer scheme you can run without buying forensic software, and what it cannot prove.
Pick Your Mark in 60 Seconds
Skip the theory. Find your document type below, copy the values into the tool, and adjust only if the preview looks wrong. Every row is a starting point for a watermark on a PDF — the angle, opacity and page range are the only three that usually need changing.
| Your document | Mark | Opacity | Angle | Position | Pages |
|---|---|---|---|---|---|
| Contract sent for review | Text: DRAFT | 20% | -30° | Center | All |
| Confidential client file | Text: CONFIDENTIAL | 18% | -30° | Center | All |
| Invoice or proposal | Logo PNG | 12% | 0° | Bottom right | All |
| Portfolio or sample pack | Text: © name | 12% | -30° | Tiled 150 × 100 pt | All |
| Ebook preview or ARC | Text: buyer + date | 15% | -30° | Center | All |
| Legal exhibit | Text: case ID + {page} | 25% | 0° | Bottom right | All |
| Internal draft, heavy scan | Text + outline | 30% | -30° | Center | All |
Two values do most of the work: opacity and position. If the document is mostly white text pages, stay at or below 25% so the body text keeps its contrast. If the pages are scanned images or photo-heavy, keep the opacity but switch the outline stroke on, because a thin grey mark disappears against texture.
The tool opens with CONFIDENTIAL in red at 30% and -30°. That is a visible starting point, not a good default for client documents. Red at 30% is heavier than the 15–25% range that keeps text readable, and red prints as a muddy grey on mono printers.
What Actually Happens Inside the Tab
Most "free watermark" sites upload your file, stamp it on a server, and delete it later. This tool does not have a server step at all, and that changes what you can and cannot expect from the output.
The tool loads pdf-lib plus fontkit into your browser, parses the PDF in memory, and appends drawing operators to each page's content stream. The mark becomes part of the page itself. When you save, a new PDF is assembled in memory and handed to the browser as a download.
pdf-lib + fontkit
The mark is written as real page content, so it prints, it survives a save-as, and it cannot be switched off from a Layers panel.
14 built-in, or your own
Helvetica, Times, Courier, Symbol and ZapfDingbats families, or a TTF/OTF you upload. Custom fonts are subset-embedded, which keeps the size increase small.
PNG or JPG
PNG is embedded with its alpha channel, so a transparent logo stays transparent. A JPG has no alpha and arrives with a white rectangle around it.
_watermarked.pdf
Every output is named after its input: report.pdf becomes report_watermarked.pdf. Batch runs keep the same rule, which matters for the per-recipient workflow later.
What this tool will not do
These are not bugs, they are design consequences. Knowing them saves an hour of confusion:
- No behind-content mode. The mark renders above text, because it is appended to the content stream. Use opacity and the outline stroke to keep it readable.
- No invisible or steganographic mark. Everything you type is visible on the page. There is no hidden identifier to recover later.
- No signature awareness. Rewriting the PDF invalidates an existing digital signature, and the tool does not warn you.
- No redaction. A watermark does not remove text. Anyone can select and copy the text underneath.
- No PDF/A repair. The output is a normal PDF. If your archive workflow needs PDF/A, validate the result before filing it.
The Six Controls Nobody Explains
The panel has more precision than most watermark tools, and almost none of it is labelled in a way that tells you what the numbers mean. Here is the mapping.
1. Nine positions, plus point offsets
The grid gives you Top, Center and Bottom rows crossed with Left, Center and Right columns. The two offset fields then move the mark in points, where 1 pt is 1/72 inch. An A4 page is 595 × 842 pt, so an offset of 20 pt moves the mark about 7 mm. Positive X moves right; positive Y moves up.
2. Font size is in points, not pixels
The default 48 pt is roughly 17 mm tall. That is right for a diagonal status stamp and too large for a corner logo caption. For a footer-style line, 10–12 pt matches body text.
3. Outline stroke is the underrated one
Outline draws a stroke around each glyph, with its own colour and a width from 0.5 to 5 pt (the engine clamps the top end to 4 pt). It costs nothing in file size because it is still text, and it is the only way to keep a mark readable over a dark photo or a noisy scan without pushing opacity into the 40% range. Light text plus a dark outline reads on almost any background.
4. Tile spacing is measured in points, and 60 pt is the floor
Tiling repeats the mark on a grid. H-Spacing and V-Spacing are the distance between instances in points, not pixels. The inputs accept 10, but the engine clamps anything under 60 pt, so typing 20 gives you 60. Start Offset X/Y shifts the whole grid, which is how you avoid a mark landing exactly on a signature line.
The tile panel includes a Rotation Increment field that is stored but never applied when the PDF is drawn. Verified in the current build: the value is read, then ignored. Leave it at 0 and set the main Rotation slider instead.
5. The Page # field has its own syntax
Leave it empty to mark every page. Otherwise it accepts single numbers and ranges, separated by commas: 1, 1-5, 1-5, 8, 12-14. Numbers outside the document are silently ignored, and a reversed range like 9-4 is swapped automatically. There is no last or even keyword, so for "everything except the cover" on a 40-page file you type 2-40.
6. Four placeholders resolve per page and per file
| Placeholder | Resolves to | Example output |
|---|---|---|
{page} | Current page number | Page 7 |
{total} | Page count of that file | 7 of 214 |
{date} | Today's date in your browser locale | 24/10/2026 or 10/24/2026 |
{f} | Source filename, with .pdf | nda_acme.pdf |
Placeholders are lowercase only. {DATE} stays literal text. Because {date} uses the browser locale, the same template can produce different formats on two machines; if a fixed format matters, type the date yourself.
A full example that works in a batch: CONFIDENTIAL · {f} · {date} · page {page}/{total}. Every page of every file gets its own resolved values.
Bonus: the four presets, and what they actually set
| Preset | Opacity | Rotation |
|---|---|---|
| CONFIDENTIAL | 25% | -30° |
| DRAFT | 20% | -30° |
| SAMPLE | 30% | 0° |
| DO NOT DISTRIBUTE | 25% | -45° |
How to Watermark a PDF in Five Clicks
The whole flow is one screen after upload. No account, no email, no waiting queue.
01 Drop the PDF
Drop one file or several. Screen 2 opens with a file row showing size and page count. The capacity card tells you the queue limit for your device before you add more.
02 Pick Text or Image
Text mode for stamps and copyright lines. Image mode for logos, where a transparent PNG is the only format that does not add a white box.
03 Set four numbers
Opacity, rotation, font size and position. Everything else can stay at default. The preview panel renders page 1 so you can see the placement before committing.
04 Limit the pages, if needed
Type 2-40 to skip a cover, or 1-5, 12 for specific pages. Leave it empty for every page.
05 Apply, then download
The result card reports original size, watermarked size, the percentage added and the processing time for that file. One file gives a direct download; several files give a ZIP.
Measured: What a Watermark Actually Costs
Every "free online" tool claims it is fast and light. These are the real numbers from this engine, measured on four test files and four mark types.
| Input | Pages | Mark | Output | Change | Per page | Time |
|---|---|---|---|---|---|---|
| 14.3 KB text | 10 | Diagonal text 48 pt, 25% | 17.0 KB | +18.6% | +270 B | 1.2 s |
| 68.9 KB text | 50 | Diagonal text 48 pt, 25% | 81.6 KB | +18.5% | +260 B | 1.4 s |
| 292.5 KB text | 214 | Diagonal text 48 pt, 25% | 346.5 KB | +18.5% | +250 B | 5.4 s |
| 68.9 KB text | 50 | Corner logo, 200 pt wide, 15% | 87.5 KB | +27.1% | +380 B | 1.9 s |
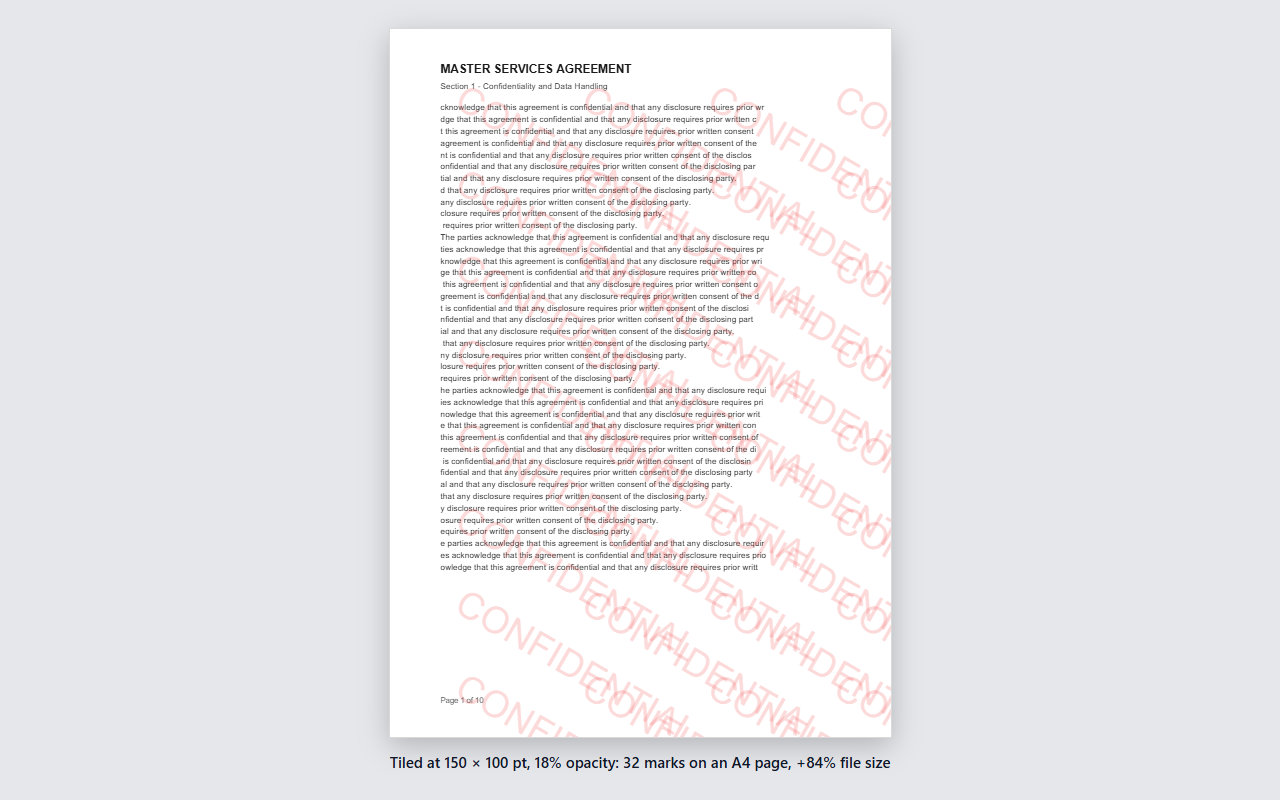
| 14.3 KB text | 10 | Tiled text, 150 × 100 pt, 12% | 26.4 KB | +84.0% | +1.2 KB | 1.5 s |
| 68.9 KB text | 50 | Tiled text, 150 × 100 pt, 12% | 129.8 KB | +88.5% | +1.2 KB | 1.6 s |
| 292.5 KB text | 214 | Tiled text, 150 × 100 pt, 12% | 557.3 KB | +90.5% | +1.2 KB | 6.8 s |
| 1.82 MB scan | 30 | Diagonal text 48 pt, 25% | 1.83 MB | +0.41% | +260 B | 1.7 s |
| 1.82 MB scan | 30 | Corner logo, 200 pt wide, 15% | 1.84 MB | +0.76% | +480 B | 1.1 s |
| 1.82 MB scan | 30 | Tiled logo, 200 × 200 pt, 12% | 1.85 MB | +1.46% | +900 B | 1.8 s |
Two patterns are worth remembering. First, on text documents the percentage stays flat near 18.5% whether the file has 10 pages or 214, because the cost is a fixed number of drawing operators per page, not a copy of the document. Second, image-heavy scans barely move, under 1.5%, because a few hundred bytes of mark is nothing next to a 60 KB page image.
Tiling is the expensive option: roughly 1.2 KB per page at 150 × 100 pt spacing, which puts about 32 instances on an A4 page. That is still small in absolute terms, and it is why text tiles are cheaper than image tiles: text reuses one embedded font, while every image instance references a heavier object.
Test files were generated with pdf-lib: three text PDFs at 10, 50 and 214 pages of 10 pt body text, and a 30-page "scan" built from 1240 × 1754 JPEG pages at quality 0.82. Each cell is one run of the live AFFLIGO tool in headless Chrome 155 on a 6.9 GB Windows laptop, timing from the click on Apply Watermark to the download being ready. Sizes are repeatable; wall-clock time varies by up to roughly 30% between runs, so read the times as "a few seconds", not as a benchmark.
Measured: Opacity Against Four Backgrounds
"Use 20 percent" is advice without evidence. I rendered the same CONFIDENTIAL mark at five opacities over four page types, then compared every pixel against the same page without a mark. Two numbers came out of it: how visible the mark is, and how much the text underneath loses.
How the measurement works
Each page is rendered twice at 150 DPI with pdf.js: once clean, once watermarked. Pixels that changed by more than 2/255 are the mark. Their average luminance is compared with the same pixels in the clean render, which gives the mark's contrast against its real local background. Text strokes are the pixels that deviate most from the page's median luminance; for those the tool reports contrast before and after, and separately for the strokes the mark actually crosses. Contrast is the WCAG relative-luminance ratio, where 1:1 means invisible and 21:1 is black on white.
| Page | Opacity | Mark contrast | Text strokes crossed | Their contrast | Page covered |
|---|---|---|---|---|---|
| White, black text | 8% | 1.12:1 | 558 px | 2.51 → 2.36:1 | 0.9% |
| White, black text | 15% | 1.19:1 | 1,043 px | 3.98 → 3.73:1 | 0.9% |
| White, black text | 25% | 1.33:1 | 1,166 px | 4.18 → 3.99:1 | 0.9% |
| White, black text | 50% | 1.74:1 | 1,297 px | 4.29 → 4.08:1 | 0.9% |
| White, black text | 80% | 2.32:1 | 1,349 px | 4.37 → 3.75:1 | 0.9% |
| Dark page, light text | 15% | 1.00:1 | 1,351 px | 11.40 → 3.69:1 | 0.8% |
| Dark page, light text | 25% | 1.06:1 | 1,374 px | 11.38 → 3.38:1 | 0.8% |
| Dark page, light text | 50% | 1.30:1 | 1,406 px | 11.38 → 2.80:1 | 0.8% |
| Light grey form | 15% | 1.18:1 | 1,119 px | 3.83 → 3.55:1 | 0.9% |
| Light grey form | 30% | 1.37:1 | 1,261 px | 3.98 → 3.75:1 | 0.9% |
| Photo page | 15% | 1.10:1 | 2,543 px | 1.27 → 1.11:1 | 0.8% |
| Photo page | 30% | 1.20:1 | 2,667 px | 1.25 → 1.00:1 | 0.8% |
Finding 1: on white pages, opacity is not the readability risk you think
Red at 25% sits at 1.33:1 against white paper, and where it crosses text those strokes go from 4.18:1 to 3.99:1, a loss of about 4 percent. Push to 80% and the strokes still measure 3.75:1. The reason is coverage: one diagonal 48 pt mark paints 0.9 percent of the page, so even at full strength it can only damage the few strokes it touches.
That is not an argument for 80%. It is an argument for understanding what you are trading. Low opacity keeps the mark polite but also faint; high opacity makes the mark loud while text stays legible. The real readability risk on a white page is a large tiled grid, where coverage jumps from 0.9 percent to roughly 30 percent and text sits under the mark everywhere rather than occasionally.
Finding 2: on dark pages, a dark mark is mathematically invisible
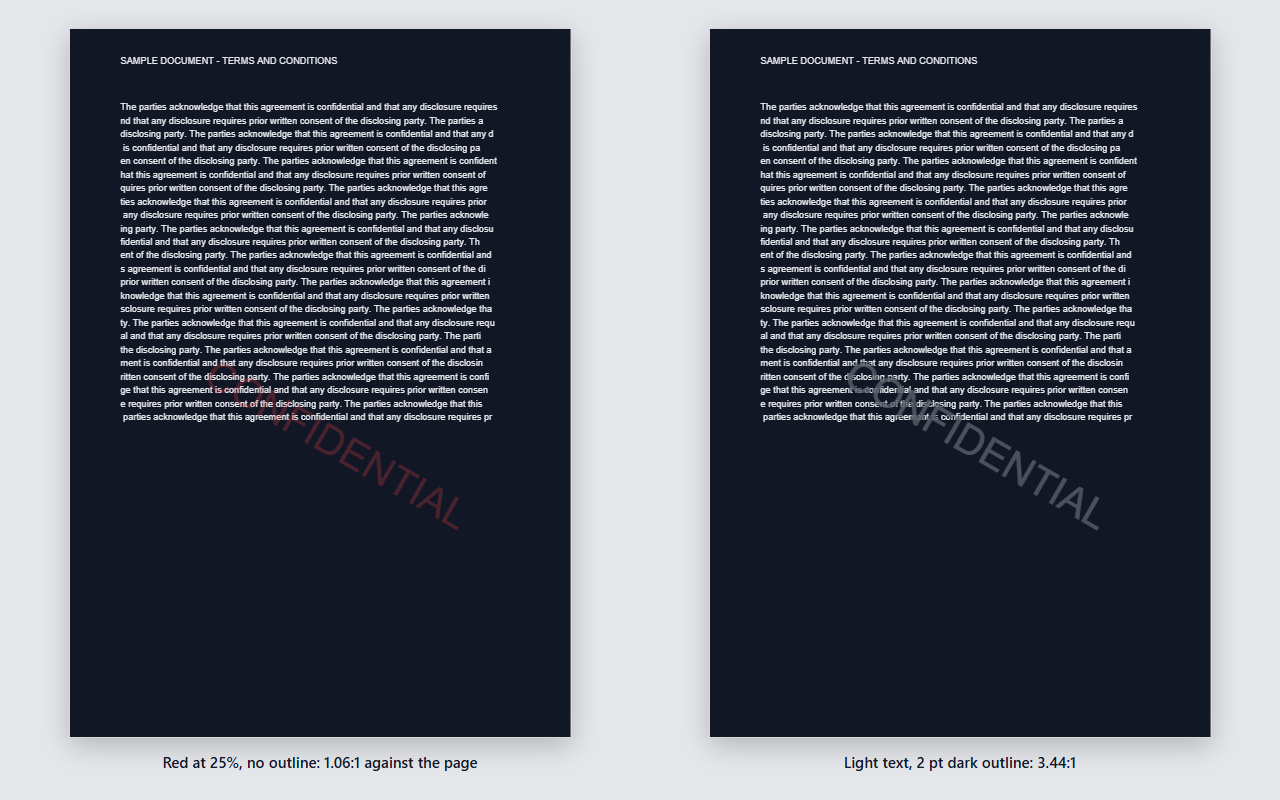
The same red mark at 15% over a dark navy page measures 1.001:1. That is not "subtle", it is zero. At 50% it reaches only 1.30:1, because a dark red over a dark background converges on the same luminance from above. This is the single most common "the watermark is not showing up" report, and it is not a bug: the colour and the background are the same brightness.
The fix is not more opacity. Switch the mark colour to a light one, or turn on the outline stroke. With a light fill and a 2 pt dark outline at 25%, the same mark measures 3.44:1, a 3.2× improvement over the unoutlined version, at 1.1 percent more page coverage.
Finding 3: a white outline on white paper is a trap
The outline that rescues a dark page actively hurts a white one. White text with a white 2 pt outline at 25% on a white page produced a mark at 1.45:1 (fine) but dragged the text strokes it crossed from 4.57:1 down to 1.98:1, because the light halo bleeds into the glyphs around it. The rule is simple: the outline must contrast with the page, not with the mark. Dark page, light outline. Light page, dark outline, or no outline at all.
Finding 4: busy imagery defeats the measurement, and that is the answer
On the photo page the clean baseline text already measures 1.13:1, which means the text was not readable before any watermark existed. The mark only moves to 1.20:1 at 30%, and the text strokes it crosses measure 1.00:1 afterwards. Numbers that bad do not mean the tool failed; they mean the test page is a gradient with high-frequency circles behind 11 pt text, and no overlay can fix an unreadable original.
What does help on imagery is the outline again: 1.59:1 for the mark, and the crossed strokes actually improve from 1.20:1 to 1.78:1, because a dark mark with a light outline separates text from a busy background. Practical rule for scanned and photographic pages: use the outline, accept that the mark is a texture rather than a sign, and put the real notice in a corner where the background is calmer.
On white and light-grey pages, anything from 8% to 50% keeps text above 3.9:1 where the mark crosses it. So choose opacity by how visible you need the mark to be, not by a fear of ruining the text: 1.12:1 at 8% is nearly invisible on screen and 1.74:1 at 50% is unmistakable. On dark or photographic pages, ignore opacity first and fix colour or outline first.
Test setup: 12 opacity runs plus 3 outline variants, each rendered at 150 DPI (1241 × 1754 px) and diffed against its own clean render. Fixtures were generated with pdf-lib: an A4 page of 11 pt Helvetica body text, the same text inverted on a dark navy background, the same on light grey with 300 scattered grey dots, and the same over a blue-to-amber gradient with 900 semi-transparent circles. Chrome 155 headless, October 24 2026. Absolute contrast values depend on the fixture; the direction and the ratios between opacities are what transfer.
Twelve Recipes With Exact Settings
Copy the row that matches your job. Every value maps to a field in the panel, so there is nothing to interpret. The first two rows are the common cases: a draft watermark for a contract in review, and a CONFIDENTIAL mark for a client file.
| Job | Mark text or logo | Size | Opacity | Angle | Position | Notes |
|---|---|---|---|---|---|---|
| NDA sent for review | DRAFT | 48 pt | 20% | -30° | Center | Stops a reviewer treating it as final. |
| Confidential client file | CONFIDENTIAL | 48 pt | 18% | -30° | Center | Readable, still below the legibility ceiling. |
| Invoice branding | Logo PNG | 180 pt wide | 12% | 0° | Bottom right | Add Y offset 24 pt so it clears the footer. |
| Proposal header | Logo PNG | 120 pt wide | 10% | 0° | Top right | Quiet ownership claim on every page. |
| Photography client proof | PROOF · {f} | 36 pt | 30% | -30° | Tiled 200 × 200 pt | Hard to crop out of a screenshot. |
| Design portfolio | © 2026 Your Studio | 32 pt | 12% | -30° | Tiled 150 × 120 pt | Low enough not to fight the artwork. |
| Ebook ARC | ARC · {f} · {date} | 28 pt | 15% | -30° | Center | Identifies the review copy and its date. |
| Course notes | Buyer email address | 24 pt | 18% | -30° | Center | One copy per buyer; see section 10. |
| Legal exhibit | CASE-2026-014 · {page} | 14 pt | 25% | 0° | Bottom right | Bates-style ID that changes per page. |
| Drawing revision | REV B · {date} | 36 pt | 20% | 0° | Bottom center | Status without covering the drawing. |
| Offer letter | DRAFT - NOT FOR DISTRIBUTION | 40 pt | 22% | -30° | Center | Long text needs the smaller size. |
| Scanned form or photo page | SAMPLE + outline | 54 pt | 35% | -30° | Center | Outline 1.5 pt in the opposite colour. |
Two adjustments cover most surprises. If the mark disappears into a busy page, turn on the outline before raising opacity. If the mark makes text hard to read, lower opacity by 5 points and raise font size instead, because a larger mark at lower opacity reads better than a small dark one.
How Watermarks Get Removed
Any guide that promises "unremovable" is selling something. There is no single PDF watermark remover that undoes every mark: there are exactly three routes, they target different mark types, and knowing them is how you choose a mark that survives the threat you actually face.
Route 1: page-content stripping
Because the mark is written into the page content stream, a script can rewrite that stream and drop the operators that draw it. Open-source tools do this at three aggressiveness levels: remove objects that are explicitly labelled as a watermark, then remove "graphical elements that appear more than once along the pages", then remove all vector graphics. That middle rule is worth pausing on: a tiled watermark is the easiest mark to identify automatically, because it repeats by definition. The research-integrity watermark-removal tool uses exactly this heuristic.
Route 2: layer toggling
Some PDF editors place a watermark on an optional content group, which appears as a layer in the viewer. That mark can be switched off from the Layers panel without touching the page content, and a few lines of PyMuPDF will disable it programmatically. Some tools mark the layer as locked, which only removes the menu item, not the option. AFFLIGO does not use layers: the mark is page content, so there is no checkbox to untick.
Route 3: raster reconstruction
Screenshot the page, crop the region, or run it through an inpainting model. Current inpainting networks rebuild the area under a visible mark convincingly enough for a casual reader, especially on flat backgrounds. This route beats every visible mark eventually, which is why visible watermarking is a deterrent and an attribution aid, not a lock.
| Mark type | Content stripping | Layer toggle | Screenshot crop | Inpainting | Photocopy |
|---|---|---|---|---|---|
| Single diagonal text | Weak | Not applicable | Weak | Weak | Moderate |
| Tiled text | Weakest (repeat rule) | Not applicable | Strong | Moderate | Strong |
| Corner logo | Weak | Not applicable | Weakest | Weak | Moderate |
| Text with outline | Weak | Not applicable | Moderate | Moderate | Strong |
| Recipient name in mark | Weak | Not applicable | Strong if tiled | Moderate | Strong |
The practical conclusion is uncomfortable but useful: tiling wins against screenshots and loses against automated stripping, while a single mark does the opposite. If your threat is a person forwarding a file, tile. If your threat is someone running a script over the PDF, no visible mark survives, so the mark's job becomes evidence rather than prevention.
Watermark remover tools: what they can and cannot do
A search for a PDF watermark remover lands on tools that wrap one of those three routes in a friendlier interface. They work when the mark is a separate object or an optional layer, because there is something to switch off. They fail when the mark was merged into the page content and the area under it is busy, which is exactly what this watermark tool produces. Rasterising the page and repainting the region is the only route that beats a flat mark, and it turns the PDF into an image: text stops being selectable, searchable and accessible.
None of the three vendors people search for by name lists a watermark remover in its tool list as of 30 October 2026. iLovePDF, Sejda and Watermarkly all offer adding a mark, not taking one off. Any PDF editor can still drop a white rectangle over a stamp, which hides it without removing anything: the text underneath stays selectable, and the page carries both objects.
If the mark is not yours, ask for the clean original before you go looking for a remover. That is a licensing question first and a technical one second.
Combine three cheap things: a mark that carries the recipient's name, a copy of the document kept in your own records, and a rule that each recipient gets a different file. Removal is easy; explaining why a leaked copy carried your name is not.
When a Watermark Is the Wrong Tool
A watermark is often used to solve a problem it cannot solve. Check this list before you spend time on settings.
Hiding sensitive data
A watermark does not remove text. The account number is still selectable and searchable underneath. Use redaction or the PDF Editor to delete content, then watermark the result.
Preventing access
If the wrong person must not open the file at all, that is encryption, not marking. Use Protect PDF with a password, and read the honest limits of PDF permissions in the password guide.
Tracking a leak automatically
Visible marks need a human to read them. Automatic attribution needs an invisible identifier and a database, which is paid forensic software, not a browser tool.
Proving ownership in court
A mark is evidence of notice, not proof of authorship. Registration, timestamps and original files do that work. Section 11 covers what a notice needs to contain.
The reverse is also true: if the goal is "this draft must not be mistaken for final" or "this sample must carry my name when it travels", a watermark is the cheapest, most effective tool available, and no other feature replaces it.
Per-Recipient Marking on a Budget
Forensic watermarking software costs thousands a year and does one thing this free tool cannot: embed an identifier nobody can see. You can still build a scheme that answers the only question that matters after a leak, which is "whose copy is this".
The scheme has four layers. Each one is cheap, and together they survive more attacks than any single mark.
Layer 1: a visible identifier in the mark
Put the recipient's name, their order number, or both, into the watermark text. A single diagonal mark with ACME LTD · ORD-4471 is enough to answer the leak question, and it takes one extra batch run per client.
Layer 2: the filename placeholder
If you name your source files after recipients, {f} writes that name into every page without retyping anything. Name the file nda_acme.pdf, set the text to CONFIDENTIAL · {f}, and the mark reads CONFIDENTIAL · nda_acme.pdf on all 40 pages. The output keeps the pattern too: nda_acme_watermarked.pdf.
Layer 3: a second mark in a second place
One centred mark is easy to crop away. Add a small corner mark in a different colour at 10–12 pt, positioned in a spot that would be awkward to remove without damaging the layout: over a header rule, next to a page number, inside a footer band. Two marks mean a thief has to find and remove both, and the corner one is usually missed.
Layer 4: the log
Keep a row per recipient: name, email, date sent, file hash, and the exact watermark string. The mark proves the copy came from you; the log proves which copy went to whom. Without the log you have a visible name but no record of when it was issued, and that gap is what a dispute turns on.
| Recipient | Watermark text | Source filename | Log row |
|---|---|---|---|
| Acme Ltd | CONFIDENTIAL · ACME · {f} · {date} | nda_acme.pdf | 2026-10-24, sha256, sent by email |
| Northwind | CONFIDENTIAL · NORTHWIND · {f} · {date} | nda_northwind.pdf | 2026-10-24, sha256, sent by email |
| Review counsel | PRIVILEGED · COUNSEL COPY · {page} | nda_counsel.pdf | 2026-10-25, sha256, hand delivery |
There is no invisible layer. Everything the tool writes is visible, selectable text that anyone can read and retype. It cannot identify a copy that was photographed and re-typed, and it cannot prove a leak in court on its own. If you need machine-readable attribution, that is a paid forensic product with a detector service, and this is not a substitute for it.
What a Mark Legally Proves
This is general information, not legal advice, and it varies by country. The short version: a watermark is notice and evidence, not ownership.
A copyright notice has a known shape
The widely used form is the symbol © or the word Copyright, the year of first publication, and the name of the owner: © 2026 Karan Kumar. Under the US Copyright Act, section 401, a notice of this shape may be placed on copies to give notice of copyright, and it defeats a defence of innocent infringement. Notice is not registration, and registration is what enables statutory damages in the United States.
A watermark reading CONFIDENTIAL is a different thing entirely. It is a confidentiality notice, not a copyright claim, and its legal weight comes from the agreement it sits inside, not from the mark.
What the mark actually supports
- Notice. The recipient cannot credibly say they did not know the document was confidential when every page says so.
- Attribution of a copy. A per-recipient mark links a specific file to a specific issue, which is the practical core of most leak investigations.
- Intent. A mark that was deliberately removed is evidence that someone took steps to remove it, which is often more useful than the mark itself.
What it does not support
It does not establish authorship, it does not create a contract, and it does not stop copying. It also does not make a document "legally protected" in any sense a lawyer would recognise. If the document matters, the paper trail matters more than the mark: drafts with timestamps, an email trail, a signed agreement, and a registration where the law provides one.
© 2026 Your Name · Confidential · Not for distribution at 12 pt, bottom centre, 18% opacity. It carries the copyright element, the confidentiality claim and the distribution restriction in one line, and it is short enough to stay readable at small size.
Print and Scan Survival
A mark that looks right on a monitor can vanish on paper. Printers, photocopiers and scanners all flatten contrast, and each does it differently.
Why the mark prints lighter than it looks
The mark is real page content, so it prints with everything else: no "background graphics" checkbox, no annotation toggle, no missing layers. What changes is the value. A 15% grey on screen is a light grey against pure white backlight; on paper the same value sits against paper white under room light, and the difference between the two is smaller than your monitor suggests. A mono laser printer then dithers it into a dot pattern, and a photocopier at 200 dpi can lose it entirely.
The measured behaviour matches: at 8% the mark is 1.12:1 against white, which is right at the edge of what survives a photocopy. At 25% it is 1.33:1, and at 50% it is 1.74:1, comfortably visible on a second-generation copy.
The one-page test
Before sending anything important, print page 1 at 100% scale on the printer you will actually use, then photocopy that page once. If the mark is still readable on the photocopy, it will survive the real run. Two settings ruin this test: "fit to page" (which rescales the mark) and any grayscale or toner-saving mode (which lightens it further).
| Output path | What happens to the mark | Safe minimum |
|---|---|---|
| Colour inkjet, 100% | Colour holds, light values stay visible | 15% |
| Mono laser, 100% | Red becomes mid-grey, dithering adds texture | 20% |
| Photocopy of a mono laser print | Light values drop out, edges soften | 30% |
| Phone photo of a screen | Moiré and glare can hide a faint mark | 25%, tiled |
| Fax or 200 dpi scan | Thin strokes disappear, thick ones survive | 35% + outline |
If the document will only ever be read on screen, ignore this section and use the lower values. Print survival is a cost: a mark heavy enough to survive a fax is heavy enough to annoy everyone reading the PDF on a laptop.
Hindi, Arabic, Tamil: Why the Export Refuses
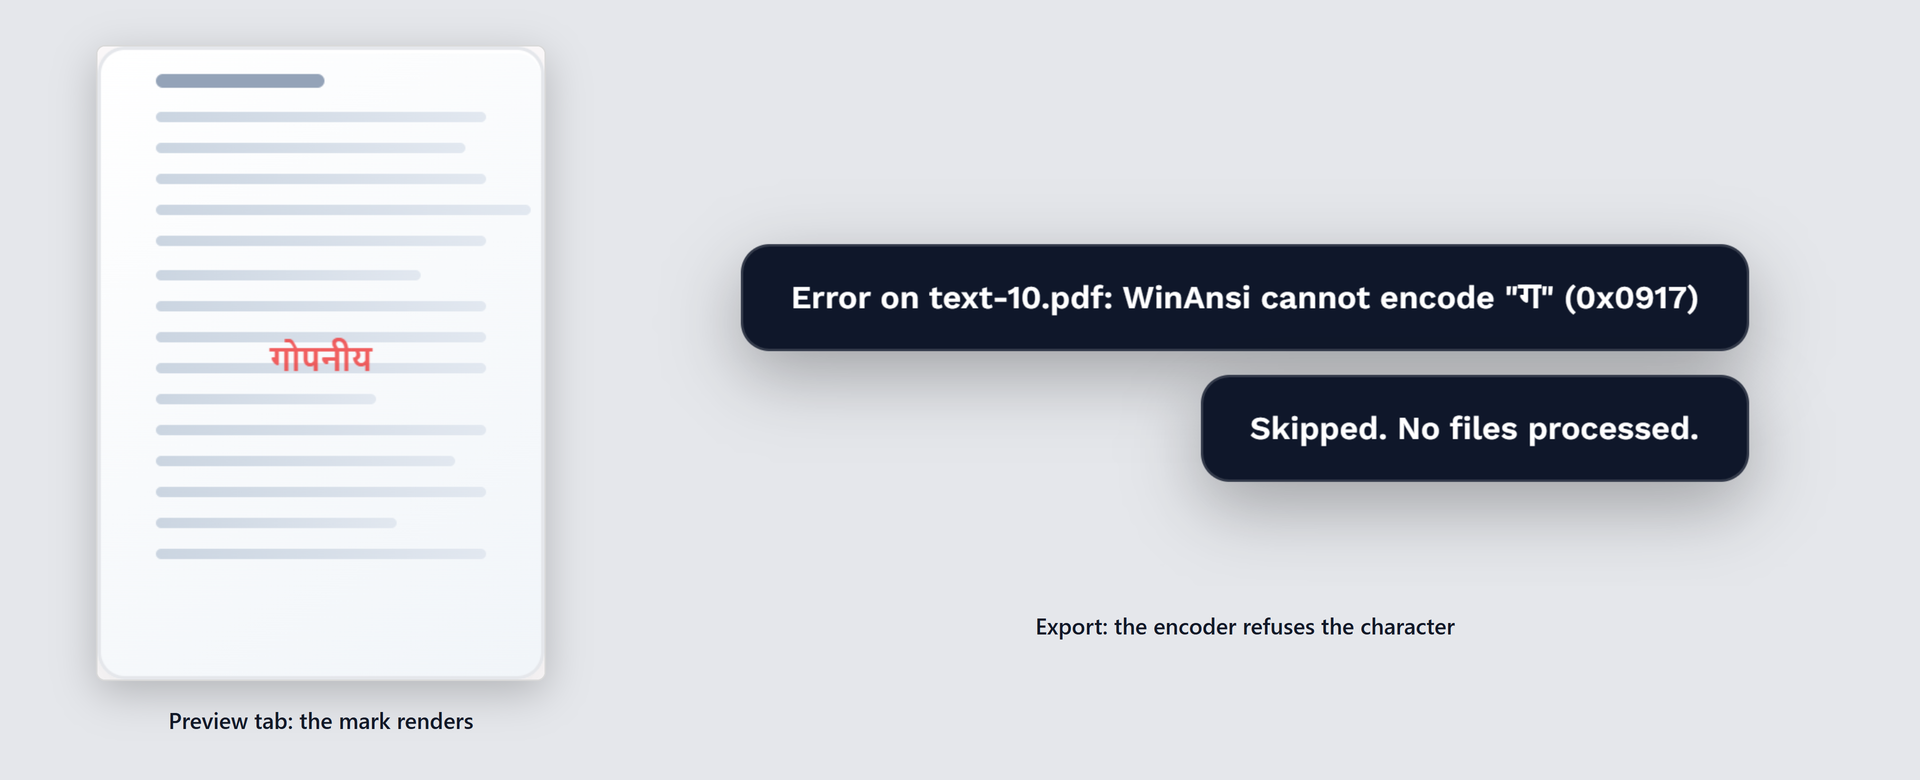
Type गोपनीय into the watermark field and the Preview tab shows it perfectly. Press Apply and nothing is produced: the run stops with WinAnsi cannot encode "ग" (0x0917). There are no boxes in the output, because there is no output.
The cause: 14 fonts, one character set
The font dropdown lists Helvetica, Helvetica-Bold, Helvetica-Oblique, Helvetica-BoldOblique, Times-Roman, Times-Bold, Times-Italic, Times-BoldItalic, Courier, Courier-Bold, Courier-Oblique, Courier-BoldOblique, Symbol and ZapfDingbats. Those are the 14 standard PDF fonts. They are not embedded in your file, because every PDF reader is required to supply them, and that is exactly why they are limited: they encode WinAnsi, which covers Latin-1 plus a handful of typographic symbols. Devanagari, Arabic, Hebrew, Tamil, Bengali, Thai, Chinese, Japanese and Korean are all outside that set.
What actually happens on export
The Preview tab is not a PDF render. It is an HTML mock: a styled div with the text, colour, opacity and rotation applied by CSS, drawn in whatever font your browser uses for that script. That is why it looks correct while the export cannot possibly succeed. The tab shows you the position and the wording, not the font.
On export, pdf-lib asks the standard font for the glyph behind U+0917 and there is none, so the encoder throws. The file is skipped, and the queue ends with "Skipped. No files processed." Measured on the 10-page test file: 14.3 KB in, zero bytes out. Nothing is silently replaced with a box character, which is better than a PDF full of rectangles, but it also means the failure is easy to miss if you are not watching the toast.
The fix: upload a font that has the glyphs
01 Pick a font with your script
Noto Sans Devanagari, Noto Naskh Arabic, Noto Sans Tamil, or any system font that renders your language correctly in a text editor. A .ttf or .otf file, not a .woff2.
02 Choose Custom Font in the dropdown
The upload control appears next to it. The file is read locally, the same way the PDF is, and fontkit is loaded to parse it.
03 Check the output, not the preview
The preview cannot tell you whether the font worked, because it never used the PDF font in the first place. Apply one page and open the result in a real viewer.
What a custom font changes
It works, at a small size cost. With Nirmala UI uploaded, the same 10-page file completed in about 3 seconds and produced a 22 KB PDF from a 14.3 KB input, roughly 55 percent larger. Almost all of that is the embedded subset: about 8 KB of glyph outlines and metrics, paid once per file. On the 214-page text file the same 8 KB would be under 3 percent, so the cost is a fixed overhead, not a per-page one.
The text layer is correct. Extracting text from that output returns गोपनीय as text, so the mark stays searchable and selectable, and the file is not a picture of a word.
A rendering caveat worth knowing. In our own test render, the subset glyphs from a variable Devanagari font drew as hollow outlines, even though the text layer was correct and the page's operator list contained only text-showing operations, with no stroke operations at all. Treat that as a renderer quirk rather than a broken file, but it is exactly the kind of thing that looks alarming in one viewer and fine in another. Open the output in the viewer your recipient uses before you send it.
No shaping engine. Arabic and Indic scripts need shaping: letters join, and vowel signs attach to consonants. pdf-lib with fontkit embeds the font and maps characters, but it does not run a full shaping engine, so joined Arabic may render with disconnected letters and Devanagari conjuncts may not form correctly. Test the exact string you will use. If shaping matters, put the translated mark into the page as an image instead: render the text in a browser or design tool, export a transparent PNG, and use image mode.
There is no bidirectional text support. Arabic and Hebrew strings are drawn in the order the characters appear in the field, so a mixed string like CONFIDENTIAL - سري may come out with the Arabic segment reversed. Keep the mark in one script per run, or use the image route.
Screen Readers and the Missing Artifact Tag
A watermark is decoration to a sighted reader and a nuisance to a screen reader, unless the PDF tells assistive technology to ignore it. This tool does not, and that has consequences worth knowing before you mark a document that someone will read with a screen reader.
What should happen
In a properly tagged PDF, content that carries no meaning is wrapped in an /Artifact marked-content sequence. The WCAG technique PDF4 exists precisely for this: artifacts such as headers, footers, page numbers and watermarks are skipped by assistive technology, so the reader hears the document, not the decoration. A real artifact is also excluded from the reading order and from text extraction.
What this tool does instead
The mark is appended to the page content stream as plain text drawing operators, with no marked-content wrapper and no structure element. There is no /Artifact tag, no alternate text, and no structure tree update. Three practical results:
- It can be read aloud. Depending on the reader and how the original was tagged, "CONFIDENTIAL" may be announced on every page, once per mark instance. With a tiled mark, that can mean dozens of repetitions per page.
- It is in the text layer. Copy-paste and text extraction include the watermark string, which is usually what you want for evidence but annoying when someone extracts a paragraph.
- It does not repair tagging. If the input PDF was untagged, the output is untagged. If it was tagged, the new content sits outside the structure tree.
What to do about it
| Situation | Recommendation |
|---|---|
| Document will be read with a screen reader | Keep the mark short, use one instance per page instead of tiling, and put the full notice in the document body where it belongs in the reading order. |
| Public sector or regulated accessibility target | Do not mark the accessible master. Keep an accessible copy without a watermark and mark only the distribution copies, or add the artifact tag afterwards in a PDF/UA tool. |
| Internal drafts only | No action needed. The mark is short, and internal readers rarely use a screen reader on a draft. |
Put the confidentiality notice in the page footer as part of the document text, and use the watermark only as the visual layer. A sighted reader sees the diagonal stamp, a screen reader hears the notice once, in the right place, at the right time. This is also better for anyone reading on a small screen.
What Breaks, and Why
Five failure modes cover almost every report. Each one has a cause you can point at, not a vague "try again".
The mark is invisible
Dark mark on a dark page. Measured at 1.00:1 for red at 15% over dark navy. Change the colour or add an outline; opacity alone will not fix it.
The mark is enormous
Font size is in points and the mark is not auto-fitted. 48 pt on an A4 page is roughly 17 mm tall; 200 pt runs off both edges. Use 36–54 pt for a diagonal stamp, 10–14 pt for a footer line.
Only some pages are marked
The Page # field is not empty. It persists between runs, so a value like 1-5 from an earlier job silently limits the next one. Clear it before every new document.
Boxes instead of letters
Non-Latin script with a standard font. The 14 built-in fonts only encode WinAnsi. Upload a TTF that contains the script.
The signature is now invalid
Any rewrite of a PDF invalidates a digital signature, and this tool rewrites the file. There is no warning. Re-sign after watermarking, not before.
Output is password-free
An encrypted input is unlocked in memory, stamped, and saved as a normal PDF. The download has no password. Re-apply protection afterwards if the file must stay locked.
Password-protected input, in detail
Encrypted PDFs go through a detection step before the mark is applied. If the file is encrypted, the tool asks for the password, keeps it for the session, and unlocks the bytes in memory. Two consequences follow, and both surprise people:
- The output is not encrypted. The password was only used to read the input. Anyone who receives the watermarked file can open it without a password.
- Owner-password permissions do not survive. Restrictions such as "no copying" or "no printing" are properties of the original encryption, and they are gone after the rewrite.
The correct order for a locked, marked file is: unlock, watermark, then lock again with Protect PDF. Doing it the other way round fails, because a locked file cannot be read by the watermark engine without the password.
A digitally signed PDF carries a byte-range digest of its own contents. Adding a watermark changes those bytes, so the signature no longer matches and every reader will show it as invalid or "document has been altered". The tool does not detect signatures and does not warn you. If the signature matters, watermark first and sign afterwards.
Troubleshooting Table
Symptom, cause, fix. Every row here comes from the actual control behaviour, not from a support script.
| Symptom | Most likely cause | Fix |
|---|---|---|
| Watermark missing on dark or photo pages | Mark colour matches background luminance | Switch to a light colour, or enable outline with a contrasting stroke colour |
| Watermark text runs off the page | Font size too large, or X/Y offset pushing it out | Reduce font size; set offsets back to 0 and reposition with the 9-point grid |
| Watermark appears twice on one page | You marked the watermarked output again | Within one run each page is stamped once, and overlapping ranges such as 1-5, 3 are collapsed. A second pass over the output stacks a second mark. |
| Nothing happens on Apply | No file in the queue, or the button is disabled | Add a PDF first; the button enables only when at least one file is loaded |
| Preview shows the old mark | Preview renders on a short debounce | Wait a moment, or nudge any slider to force a redraw |
| Tile spacing ignores your number | Engine clamps tile spacing to a 60 pt floor | Use values of 60 pt or more; 150 × 100 pt is a good default |
| Rotation Increment does nothing | Dead control in the current build | Set the main Rotation slider instead |
{DATE} appears literally | Placeholders are lowercase only | Use {date} |
Page range like last-3 is ignored | Only numbers and numeric ranges are parsed | Use real page numbers: 12-14 |
| Output PDF asks for a password | Not possible from this tool | The output is never encrypted; if a password is requested, you are opening the original file |
| Hindi or Arabic shows boxes | Standard font has no glyphs for the script | Upload a TTF/OTF that contains the script |
| Download is a ZIP | More than one file in the queue | Process a single file for a direct PDF download |
AFFLIGO vs Adobe, Sejda, iLovePDF and Watermarkly
A fair comparison has to admit where the other option wins. Here is where each one is genuinely better, starting with the desktop suite, then the three online tools people search for by name.
| Capability | AFFLIGO | Adobe Acrobat | Typical free online tool |
|---|---|---|---|
| Where processing happens | Your browser tab | Your machine (desktop app) | Their server |
| Upload required | No | No | Yes |
| Behind-content watermark | No, always on top | Yes, layer order is configurable | Rarely |
| Text and image marks | Yes | Yes | Usually text only |
| Tile spacing control | Yes, in points | Yes, with relative scale | Preset tiles only |
| Per-page ranges | Numbers and ranges only | Full expression support | Usually all pages |
| Placeholders | 4 ({page} {total} {date} {f}) | Yes, plus metadata fields | Rarely |
| Invisible forensic mark | No | No (separate product) | No |
| Artifact tagging for screen readers | No | Yes | No |
| Batch limit | Adaptive, up to 1 GB total on high-memory devices | Disk-bound | Often 5–20 files or 10–25 MB |
| Price | Free, no account | Subscription | Free with limits, ads, or an account wall |
The three online tools people search for
Every cell below was read off the vendor's own tool page on 30 October 2026, not from a review site. Where the page did not say, the cell says so instead of guessing.
| Tool | Where the file goes | Tile | Behind the text | Page range | Free-tier limit |
|---|---|---|---|---|---|
| iLovePDF | Uploaded to their servers, the page shows upload speed and progress | Not stated on the page | Yes, layer over or below the content | Yes, from page to page | Not stated on the tool page |
| Sejda | Uploaded, then "automatically deleted after 2 hours" | No tile or repeat control listed | Not listed | Yes, a custom page range | "Up to 200 pages or 50 MB and 3 tasks per hour", one file per task |
| Watermarkly | On your device, "we do not send your files to our servers" | Yes, a Tile option | Yes, "place the watermark behind the text" | Yes, Page Range settings | No page or size limit stated on the page |
| AFFLIGO | In your browser tab | Yes, spacing in points plus a start point | No, the mark always sits on top | Yes, numbers and ranges | No file count, the queue is capped by device memory |
Choose Acrobat when you need the mark behind the content, when you need a real page-range expression language, or when the output must be PDF/UA tagged. Choose this tool when the file should not leave your machine, when you want tile spacing in real units, or when you need to stamp a hundred files without an account. Avoid any upload-based tool for anything confidential: the file leaves your device, and you have only their word for what happens to it.
Batch Runs and a 12-File Checklist
The queue is where a browser tool usually falls over. Here is the measured behaviour, then the order of operations that avoids the four mistakes people make in a batch.
Measured: 12 files, 120 pages
| Measure | Result |
|---|---|
| Files in the run | 12 PDFs, 10 pages each, identical content |
| Total pages processed | 120 |
| Input total | 172.0 KB |
| Processing time | 7.2 s (16.6 pages per second) |
| Download | One ZIP, 186.7 KB, 12 entries |
| Mark used | {f} - CONFIDENTIAL, 36 pt, 20%, -30°, centre |
Two details matter more than the timing. First, the ZIP came out larger than the sum of its inputs (186.7 KB vs 172.0 KB) even with DEFLATE, because each watermarked PDF is slightly bigger than its source and ZIP cannot recover that. Second, the filename placeholder resolved per file, so each of the 12 outputs carried its own source name in the mark, which is the whole point of batching with {f}.
The queue has no fixed file-count limit. Instead the tool checks available memory and shows a capacity card; on a high-memory device the ceiling is around 1 GB of total input. In practice the limit you will hit first is patience, not the counter: a 214-page file took 5.4 s on its own, so 10 of those is roughly a minute of tab time.
The order of operations
01 Fix the content first
Watermark last among the content edits. Merging, splitting, rotating, page numbers and compression all rewrite the file, and any of them applied after the watermark can move or re-render the mark.
02 Set the mark once, verify on page 1
The settings apply to every file in the queue. Process one file, check the result, then add the rest. Changing a control after a batch has run does not retroactively fix the files already in the queue.
03 Name the sources for the placeholder
{f} reads the source filename, so nda_acme.pdf produces a mark that identifies Acme and an output called nda_acme_watermarked.pdf. Rename before uploading, not after downloading.
04 Sign and lock afterwards
Watermarking invalidates signatures and strips encryption. Do both at the end, on the final watermarked files.
Leftover page range. A 1-5 from the last job silently limits the new batch. Mixed page sizes. A 48 pt mark is right for A4 and oversized on a 300 × 400 pt receipt, so batches of mixed formats need one run per size. ZIP expectations. The download is a ZIP when more than one file is queued, which many corporate mail filters block. Tab sleep. Closing or backgrounding the tab mid-run stops the work, because the processing happens in that tab.
Frequently Asked Questions
No. The watermark is drawn by pdf-lib inside your browser tab. The file never leaves your device, nothing is stored, and no account is needed.
Logos 10 to 15 percent, status text such as CONFIDENTIAL or DRAFT 15 to 25 percent, samples and previews 30 to 40 percent. Above 50 percent body text drops below a readable contrast on white pages.
pdf-lib appends the mark to the page content stream, so it renders above existing content. There is no behind-content mode. Keep opacity at 15 to 25 percent, or use the outline stroke so the mark stays readable without blocking text.
The 14 built-in PDF fonts only encode Latin-1 characters. Upload a TTF or OTF font that contains your script under Custom Font, and the text is embedded through fontkit.
Yes. A determined person can strip page-content marks with PDF editing scripts, disable layer-based marks, or paint over visible marks with image inpainting. A watermark is a notice and a deterrent, not encryption.
Only in a narrow sense. Open-source scripts can strip a mark that was written into the page content, and any PDF editor can cover one with a shape, but neither restores the page: the stripping heuristics can take real graphics with them, and a cover leaves the original text underneath. Section 8 covers each route.
Yes. The tool rewrites the PDF, which invalidates any existing digital signature. There is no signature warning in the current build, so remove or re-apply the signature yourself after watermarking.
In our tests a diagonal text mark added about 18.5 percent to text PDFs at 10, 50 and 214 pages, a tiled text mark added 84 to 90 percent, and image-heavy scans grew under 1.5 percent.
Yes, one copy per recipient with their name, order ID and date in the mark. Batch processing plus the {f} filename placeholder keeps large runs organised. The tool does not embed invisible steganographic identifiers.
Yes, because the mark is real page content rather than an annotation or layer. Print one page at 100 percent first, since a 15 percent grey mark can fade in photocopies and on low-toner printers.
No. It is notice and evidence, not enforcement. For a copyright notice include the symbol or the word Copyright, the publication year and the owner name. This is general information, not legal advice.
Key Takeaways
- Opacity is a visibility dial, not a readability dial. On white pages a 25% mark costs the text strokes it crosses about 4% of their contrast, so pick opacity by how loud you need the mark.
- On dark pages a dark mark is mathematically invisible: red at 15% measured 1.00:1. Change the colour or add an outline before you touch opacity.
- A white outline on white paper is a trap. The stroke must contrast with the page, not with the mark, or it drags crossed text down to 1.98:1.
- A diagonal text mark costs about 18.5% of the original file size at 10, 50 and 214 pages. Tiling costs 84–90%. Scans barely move, under 1.5%.
- Tile spacing is in points with a 60 pt floor, so typing 20 gives you 60. Rotation Increment is a dead control in the current build.
- The Page # field only understands numbers and ranges, and it persists between runs. Clear it before every new document.
- A watermark is notice and evidence, not protection. Tiling beats screenshots and loses to automated stripping, because the repeat rule identifies it.
- Signed PDFs break silently and encrypted inputs come out unlocked. Watermark first, sign and lock afterwards.
Watermarking is one step in a chain. These handle the rest: