- OCR (Optical Character Recognition) extracts editable text from photos, scans, and screenshots
- Accuracy is decided by three image properties -- sharpness, angle and contrast -- not by the language setting
- A phone photo has no DPI: what matters is pixels per character, and filling the frame is the biggest free win
- Angle detection tests every angle from -15 to +15 degrees in 0.5 degree steps and rotates only at 0.5 degrees or more
- Light mode does not binarise: thresholding a clean scan measured a 0.67% character error rate against 0.00% in greyscale
- Clean, high-resolution images achieve 95-99% OCR accuracy
- 300 DPI is the optimal resolution for most OCR tasks
- AFFLIGO processes images entirely in your browser -- no uploads, complete privacy
- 4 preprocessing modes: Light, Medium, Aggressive, None
- 8 languages supported: English, Hindi, French, German, Spanish, Portuguese, Arabic, Russian -- pick before running
- Export as TXT for quick access or PDF for searchable documents
Why Your Photo Reads Wrong: The Sharpness, Angle and Contrast Fix Table
Three properties of the image decide whether OCR succeeds. Everything else is a symptom of one of them.
An OCR engine does not "read" a photo. It measures glyph shapes against a model of what a character should look like, and it is only as good as the image it was handed. Three properties matter, in this order: sharpness (how many pixels each character occupies), angle (whether the baselines are level), and contrast (whether ink is clearly separated from the background). Get one wrong and the engine does not fail loudly — it returns confident, plausible, wrong characters. That is why "OCR is inaccurate" is almost never the diagnosis, and why tweaking the language setting is usually wasted effort.
Phones have no DPI setting, and the number you see in a photo's properties is meaningless for OCR. What actually matters is pixels per character height. A 12-megapixel phone camera gives you roughly 4000 px across the frame, so a receipt filling the frame delivers around 30–60 px per character line — comfortably legible. The same receipt shot from across a café table, where it occupies a fifth of the frame, drops to around 6–10 px per character, and the engine is being asked to recognise a letterform from fewer pixels than it has features. Fill the frame with the text. That single habit does more for accuracy than any setting in the tool.
| Defect in the image | What the recogniser sees | The tell-tale symptom | What fixes it |
|---|---|---|---|
| Too few pixels per character (shot from too far away) | A letterform smears across 6-8 pixels, so a bowl and a curve become the same shape | Words come out as plausible but wrong strings; 0/O and 1/l interchange freely; totals lose a digit | Move closer until the text fills the frame. No preprocessing invents detail that was never captured |
| Motion blur (shaky hand) | Edges smear in one direction, and the character's true shape is unknown | Characters that are half a letter; random substitutions throughout | Restabilise, or use a faster shutter. There is no filter for blur |
| Keystone distortion (camera at an angle) | The text is correct but trapezoidal, so a straight line of text curves in the image | Text at the bottom of the frame reads worse than the top | Photograph parallel to the page, or use the camera's document-scan mode which corrects the perspective |
| Shadow or glare across the page | Local contrast collapses where the light falls off | Whole lines or half-lines vanish; the shadowed corner returns nothing | Move the light so it falls evenly, or shade the lens with your hand |
| Tilt of 2-5 degrees | The baseline drifts within a single line, so one word's tail overlaps the next word's head | Characters merge and split unpredictably; a single field reads correctly while its neighbours are garbage | Deskew before recognition — or straighten the photo before you take it |
| JPEG artefacts | 8×8 block compression leaves ringing around every glyph, which reads as extra strokes | Phantom characters, doubled strokes, letters with spurs | Save as PNG where you can; crop tighter to reduce the block grid |
| Light grey text on white | Ink and background fall into the same grey band | Entire lines disappear, or the page returns nearly empty | Increase contrast, or re-shoot with stronger light |
| Correct image, wrong language selected | The model is looking for letterforms that are not present | Output is near-empty, or every character is a plausible substitute | Set the language explicitly. This is the one cause no image fix can solve |
The Image to Text tool runs a fixed pipeline on every image before the recogniser sees it, and these are the actual engine settings:
1. Upscale small images. If an image is under 1000 px on either edge, it is scaled up toward 2000 px — up to 3× — but only when the scale factor exceeds 1.2. This is what rescues a receipt shot from across the table. It enlarges the pixels; it does not recover detail the lens never resolved.
2. Grayscale and auto-contrast. Colour is dropped using the luma weights (0.299 R + 0.587 G + 0.114 B), then the luminance range is stretched by clipping 1% from each end. If the whole image spans less than 30 grey levels — a flat, washed-out shot — the stretch is skipped rather than amplifying noise into a mess.
3. Angle detection and correction. The engine tests every angle from -15° to +15° in 0.5° steps, building a horizontal-projection histogram of the dark pixels at each angle and scoring it by how peaky it is — the sum of squared bin counts, because a level page gives a sharp peak and a tilted one does not. The best angle wins, and the image is rotated only if the detected tilt is 0.5° or more.
4. Optional denoise, sharpen and threshold. Those three steps belong to the Medium and Aggressive modes, and they are the only ones that turn the image black-and-white.
| Mode | Pipeline that actually runs | Binarises? | Use it for |
|---|---|---|---|
| Light | Grayscale → auto-contrast | No | Screenshots, digital text, well-lit photos of clean documents |
| Medium | Grayscale → auto-contrast → median filter (radius 1) → sharpen (0.3) → adaptive threshold (block 15, C 8) | Yes | Phone photos of documents with slight shadows or speckle |
| Aggressive | Grayscale → auto-contrast → median filter (radius 2) → sharpen (0.6) → angle detect and rotate → adaptive threshold (block 21, C 10) | Yes | Old documents, low-contrast print, tilted pages, fax noise |
| None | Raw image, no processing at all | No | Perfectly clean, perfectly straight digital images — where no cleanup is better than cleanup |
Thresholding is the step that turns a grey image into a black-and-white one, and it is where accuracy is most often lost. The engine was tested on clean images with a forced adaptive threshold and measured a character error rate of 0.67%, against 0.00% for the same image left in grey. Binarising a clean image destroys the subtle grey edges the recogniser uses to tell one character from another — the tool lost accuracy it already had. That is why Light stops at grayscale and auto-contrast, and why thresholding is reserved for Medium and Aggressive.
| What you control before uploading | Why it matters more than any setting |
|---|---|
| Fill the frame with the text | It is the single biggest accuracy lever, and it is free. More pixels per character fixes every resolution complaint at once |
| Hold the camera parallel to the page | Keystone distortion makes the bottom of the frame worse than the top; a flat photo removes the problem entirely |
| Even light, no shadow | Shade the lens with your other hand if you must. A hard shadow across a line is unrecoverable |
| Steady hands or a brace | Motion blur is the one defect no filter can repair — the information is gone |
| PNG over JPEG | JPEG's 8×8 blocks put ringing around every glyph, and the recogniser reads the ringing as extra strokes |
| Crop to the text area | Fewer pixels of background means more pixels per character, and it is also faster |
History of OCR: From 1920s to AI-Powered 2026
How OCR evolved from reading aids for the blind to deep-learning-powered text extraction.
The concept of machines reading text dates back to 1914 when Eduard Tallin created "Reading Machine" for the blind. But modern OCR truly began in the 1950s-1960s with David Shepard's "Gismo" and the development of the first commercial OCR systems.
| Era | Development | Impact |
|---|---|---|
| 1914 | Eduard Tallin's Reading Machine | First concept of machine text reading |
| 1950s-60s | David Shepard's Gismo, first commercial OCR | Practical text recognition begins |
| 1970s | Ray Kurzweil's omni-font OCR | Reading machines for the blind, USPS mail sorting |
| 1990s | Tesseract OCR (HP Labs) | Open-source OCR foundation, later acquired by Google |
| 2000s | Google Cloud Vision, Azure Cognitive Services | Cloud-based OCR with deep learning |
| 2015+ | LSTM neural networks in Tesseract 4/5 | Dramatic accuracy improvement, 100+ languages |
| 2020s | Browser-based OCR via WebAssembly, AI-enhanced engines | Private, no-upload OCR runs entirely in your browser |
| 2026 | Multi-modal AI OCR, real-time extraction | Near-human accuracy, handles complex layouts and handwriting |
Modern OCR engines like Tesseract 5, Google Cloud Vision, and browser-based engines using WebAssembly recognize text in 100+ languages with accuracy past 99% on clean documents. Browser-based processing keeps that accuracy with the pixels staying on your machine — the privacy win that matters for receipts, IDs and medical papers.
How OCR Engines Actually Work
The technical pipeline from image pixels to extracted text -- preprocessing, detection, recognition, and post-processing.
Understanding how OCR works helps you optimize your images for better results. The process follows a 4-stage pipeline:
Image Preprocessing
The engine cleans the image before recognition. This includes upscaling small images, grayscale conversion, contrast enhancement, deskewing (straightening tilted text), noise removal, and — in the heavier modes only — binarization (converting to black and white). This is where preprocessing modes like Light, Medium, and Aggressive come in. Binarization is deliberately reserved for Medium and Aggressive, because forcing it onto a clean image measurably reduces accuracy. The full pipeline and threshold comparison shows exactly what each mode runs.
Text Detection & Segmentation
The engine identifies where text exists in the image. It detects lines of text, breaks them into words, and segments individual characters. Modern engines use connected component analysis and edge detection to handle varying fonts and sizes.
Character Recognition
Each segmented character is compared against trained patterns. Modern OCR uses LSTM (Long Short-Term Memory) neural networks trained on millions of text samples. The engine assigns a confidence score (0-100) to each recognized character based on how certain it is.
Post-Processing & Refinement
The engine checks results against dictionaries, fixes common misreads (like "0" vs "O" or "l" vs "1"), structures paragraphs, and handles line breaks. Some engines also apply spell-check and context-aware correction to improve output quality.
When OCR returns a confidence score, it tells you how certain the engine is about each character. Scores above 85% are highly reliable. Scores between 60-85% may need review. Below 60% usually means the engine guessed -- always check these characters manually.
Step-by-Step: Extract Text from Images
Drop the image, pick the language, choose a cleanup mode, extract, copy — the full run in five moves.
AFFLIGO's OCR processes images entirely in your browser using WebAssembly. Your files stay on your machine. Here's how to use it:
Upload Your Image
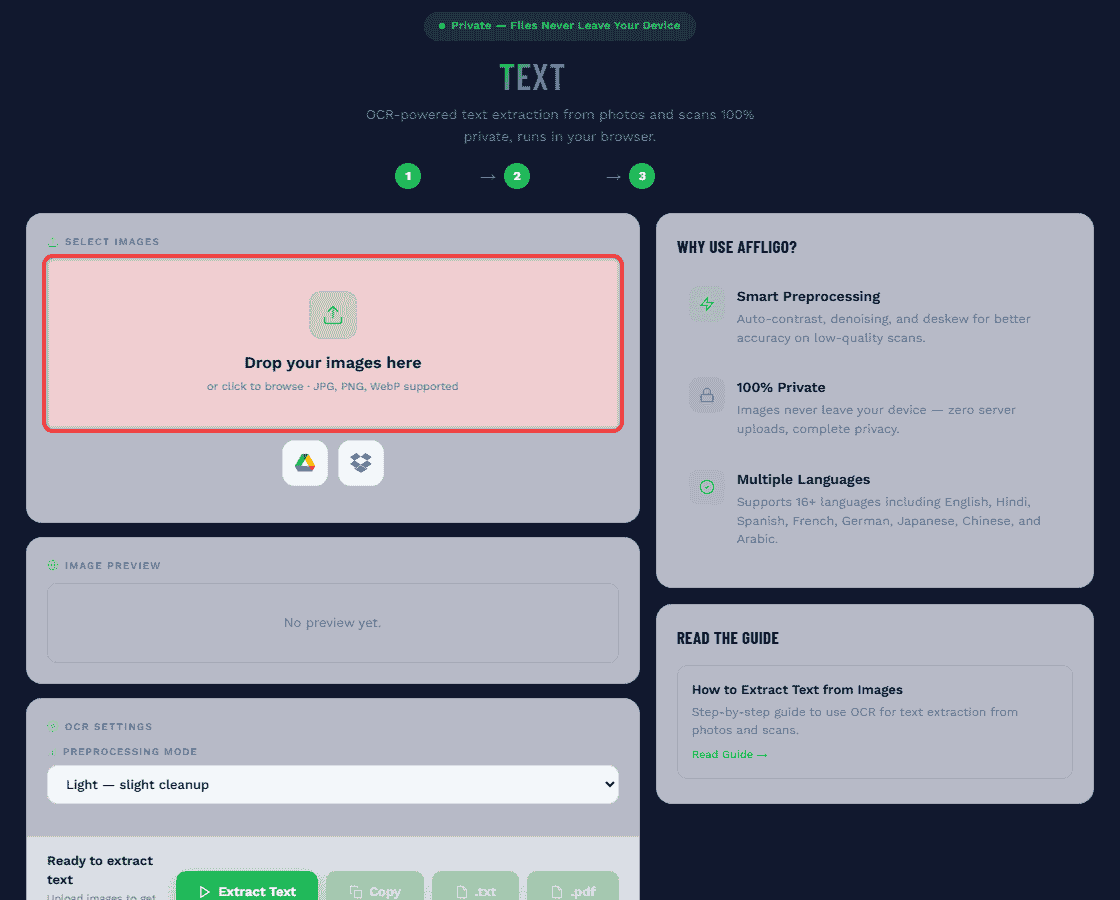
Drag and drop your JPG, PNG, or WebP image into the upload zone, or click to browse. You can also import directly from Google Drive or Dropbox. The tool supports multiple images at once for batch processing.
Preview Your Image
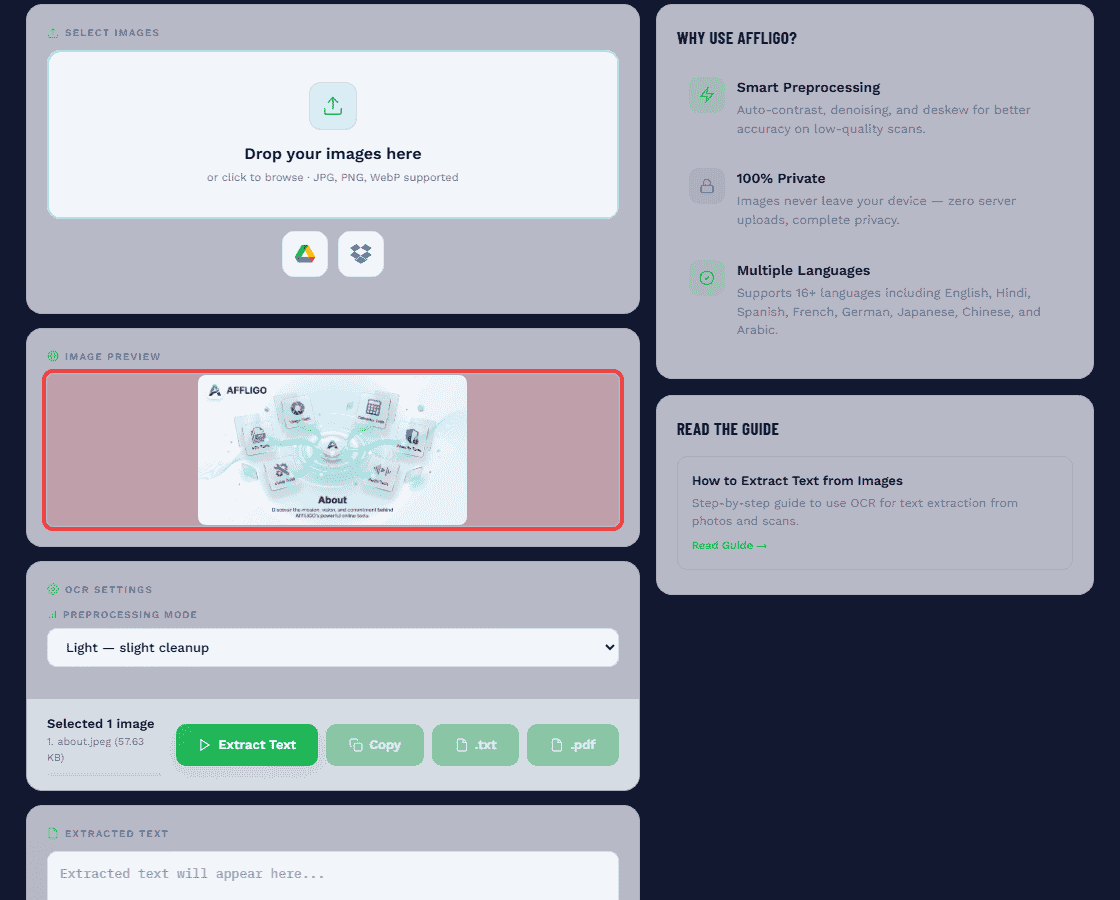
Check the image preview to confirm it loaded correctly. Make sure text is upright and readable. If the image is rotated or skewed, consider rotating it before uploading for better results.
Choose Preprocessing Mode
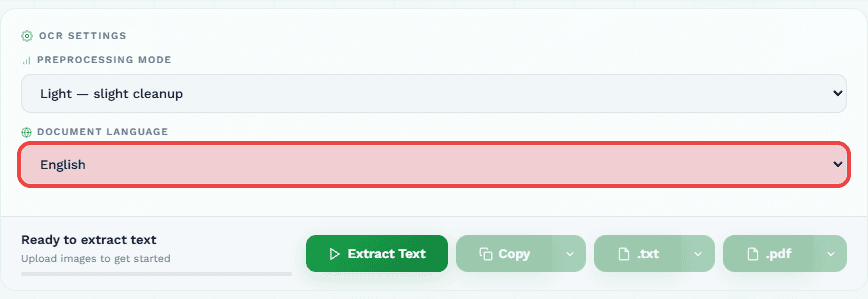
Select from 4 modes based on your image quality:
Light -- slight cleanup for clean screenshots
Medium -- denoise + threshold for average scans
Aggressive -- full cleanup + deskew for poor scans
None -- raw image, no preprocessing
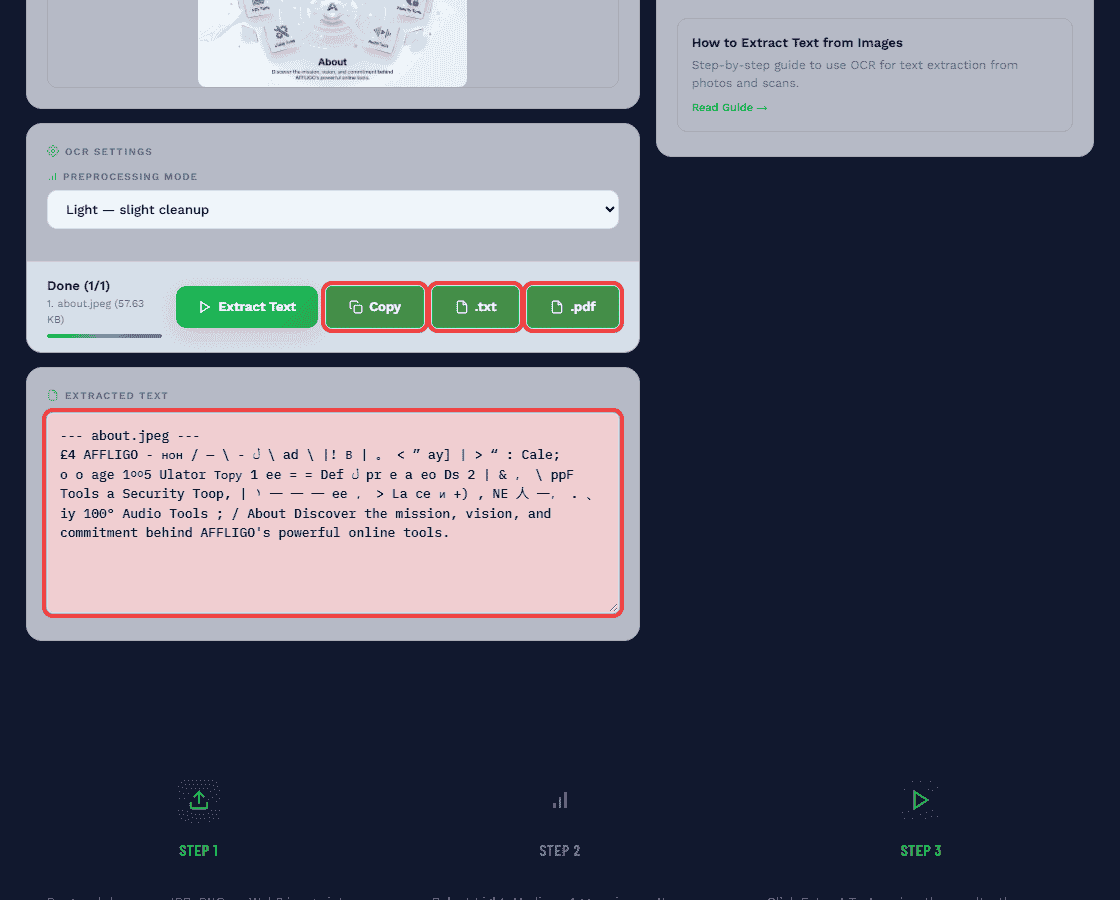
Extract Text
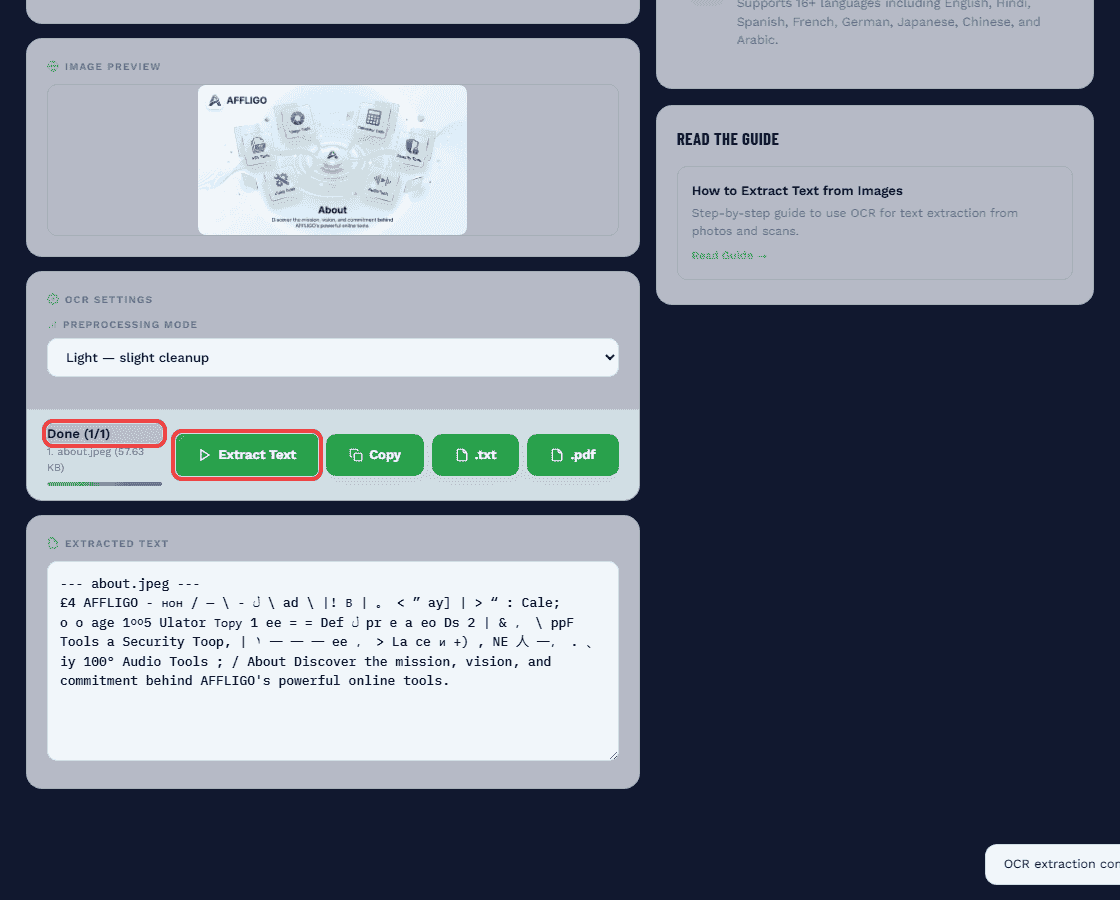
Click the Extract Text button. The OCR engine processes your image entirely in your browser -- nothing is uploaded to any server. Processing takes 2-10 seconds depending on image size and text density.
Copy or Download
Review the extracted text in the output area. Fix any character errors you notice. Then copy to clipboard for instant use, or download as TXT (plain text) or PDF (searchable document).
Preprocessing Modes Explained
When to use Light, Medium, Aggressive, or None -- and what each mode does to your image.
Preprocessing is the most important factor in OCR accuracy. The right mode can improve results by 20-30% on imperfect images. Here's how each mode works:
| Mode | What It Does | Turns the image black & white? | Best For |
|---|---|---|---|
| Light | Upscale if small, grayscale, auto-contrast stretch | No | Clean screenshots, digital text, well-lit photos of clean documents |
| Medium | Light, plus median denoise, sharpening, and local adaptive thresholding | Yes | Average scans, phone photos of documents, slight shadows |
| Aggressive | Medium, plus stronger denoise and sharpening, angle detection and rotation | Yes | Poor scans, skewed documents, low-contrast text, old documents |
| None | No preprocessing -- raw image data | No | Already-clean digital images, when you want full control |
Start with Light for screenshots and Medium for photos of documents. If accuracy is poor, try Aggressive. Only use None if the image is already perfectly clean and high-contrast. And do not jump straight to Aggressive on a clean image: thresholding a clean scan measured a 0.67% character error rate against 0.00% in greyscale, so the heavier mode can be less accurate. The full pipeline breakdown shows the exact steps behind each mode.
Supported Image Formats
Which formats work best for OCR -- and why PNG is the gold standard.
PNG (Recommended)
Best for OCR. Lossless compression preserves every pixel of text detail. No compression artifacts. Ideal for screenshots, scanned documents, and any text-heavy images.
JPG/JPEG
Acceptable for high-quality scans. Avoid heavy compression (low quality settings) as it creates artifacts around text edges. Use quality 80%+ for best OCR results.
WebP
Modern format with good quality at smaller file sizes. Offers lossless mode for perfect quality. Supported by all modern browsers and OCR engines.
When in doubt, use PNG. It's the safest format for OCR because lossless compression means zero detail loss. JPG is fine for photos of documents if the quality setting is high enough.
OCR Languages: 8 Supported
Which languages work with OCR, and how to get the best accuracy for each script type.
AFFLIGO's OCR supports 8 languages. Pick your document language in the dropdown before running -- the model (1-4MB) downloads on first use and stays cached, so repeat runs even work offline. The engine uses Tesseract.js, a JavaScript port of Google's industry-standard open-source OCR engine.
| Language | Script | Accuracy Range |
|---|---|---|
| English | Latin | 95-99% |
| Hindi | Devanagari | 88-96% |
| French | Latin | 95-99% |
| German | Latin | 95-99% |
| Spanish | Latin | 95-99% |
| Portuguese | Latin | 95-99% |
| Arabic | Arabic (RTL) | 85-93% |
| Russian | Cyrillic | 90-96% |
One language per run. Choosing the right language matters: an English model reading German text will miss every umlaut. For mixed-language documents, run the dominant language first.
How to Get Best OCR Accuracy (10 Tips)
Practical tips to maximize OCR accuracy -- from image preparation to post-processing.
Shoot at 300+ DPI
300 DPI is the sweet spot for scans. For small fonts or complex documents, use 400-600 DPI. Below 200 DPI causes significant accuracy drops. Phone photos work well when sharp and evenly lit — hold steady, fill the frame with the page, and avoid shadows (phone "DPI" is not a real setting; resolution and focus matter).
Ensure Good Lighting
Even, bright lighting across the entire document. Avoid shadows, glare, and hotspots. Natural daylight works best. If using a lamp, position it to avoid shadows on the text.
Keep Text Straight
Hold the camera parallel to the document to avoid keystone distortion. Skewed text reduces accuracy by 15-25%. Use your phone's document scanning mode which auto-corrects perspective. I once photographed a receipt at a slant on a café table — the engine misread the total until I retook it flat.
Crop to the Text Area
Remove unnecessary background. Cropping to just the text area helps the engine focus and improves both speed and accuracy. Include a small margin around the text.
Use High Contrast
Dark text on light background works best. If text is light gray on white, increase contrast before uploading. Avoid colored text on colored backgrounds.
Pick the Right Language
Select your document language from the dropdown before running -- English, Hindi, French, German, Spanish, Portuguese, Arabic, or Russian. The correct model is what makes accented characters come out right.
Choose the Right Preprocessing Mode
Start with Light for clean images, Medium for average scans, Aggressive for poor quality. The right mode can improve accuracy by 20-30%.
Use PNG Format
PNG's lossless compression preserves every pixel detail. JPG is acceptable at high quality (80%+) but avoid heavy compression which creates artifacts around text.
Review and Correct
Always review OCR output. Check for similar-looking characters (O/0, l/1, rn/m). Fix punctuation and line breaks. Use spell-check to catch remaining errors.
Try Multiple Passes
For critical documents, try different preprocessing modes and compare results. Sometimes Medium works better than Aggressive, or vice versa, depending on the specific image.
OCR for Scanned Documents
How to digitize paper records, contracts, and multi-page documents with OCR.
Scanned documents are one of the most common OCR use cases. Whether you're digitizing paper records, extracting text from contracts, or making old documents searchable, OCR transforms static images into editable, searchable text.
Single-Page Scans
Upload directly to OCR. Use Medium or Aggressive preprocessing for best results. Export as TXT for editing or PDF for searchable archives.
Multi-Page Documents
This tool takes one image per run (JPG/JPEG, PNG or WebP, up to 30MB), not PDFs. For multi-page PDFs, use the OCR PDF tool — or export pages as JPG/PNG first. Keep scanning quality consistent across pages.
Archival Quality
For permanent records, scan at 400+ DPI in grayscale. This ensures OCR accuracy today and in the future as engines improve.
After OCR, use Find & Replace in your text editor to fix common OCR errors. For example, replace "rn" with "m" if you notice the engine confused these characters, or fix specific proper nouns that were misread.
OCR for Screenshots
Why screenshots are ideal for OCR -- and how to extract text instantly from any screen capture.
Screenshots are the easiest OCR use case because they have perfect resolution and sharp text. Unlike photos of documents, screenshots have no perspective distortion, no shadows, and no lighting issues. They often achieve near 100% accuracy.
Web Content
Extract text from websites, articles, or social media posts you've screenshotted. Great for saving quotes, references, or research data.
Error Messages
Capture and extract error messages for debugging, support tickets, or documentation. Copy the exact text without retyping.
App & Software UI
Extract text from application interfaces, settings screens, or configuration panels for documentation or troubleshooting.
Built-in OCR on modern OS: Windows 11 has Snipping Tool OCR, macOS has Live Text in Preview/Photos, and mobile devices have Google Lens (Android) and Live Text (iOS). For batch processing or privacy-sensitive screenshots, use browser-based OCR.
OCR for Handwritten Text
What's possible with handwritten text recognition in 2026 -- and when to expect errors.
Handwritten text recognition uses ICR (Intelligent Character Recognition), an advanced form of OCR that applies machine learning to recognize handwriting. Accuracy varies significantly based on handwriting quality.
| Handwriting Type | Accuracy Range | Tips |
|---|---|---|
| Print Block Letters | 85-92% | Write in clear, separate block letters. Use dark ink on white paper. |
| Neat Cursive | 70-85% | Consistent letter size and spacing helps. Avoid flourishes. |
| Mixed Print/Cursive | 65-80% | Stick to one style. Consistency is key. |
| Messy/Quick Writing | 50-70% | Manual correction likely needed. Use OCR as a starting point. |
For best handwriting OCR results: use dark pen on white paper, write in block letters (not cursive), maintain consistent letter size, leave space between words, and ensure good lighting when photographing.
OCR vs Manual Typing
Speed and accuracy comparison -- when OCR wins and when manual is better.
| Factor | OCR | Manual Typing |
|---|---|---|
| Speed | 2-10 seconds per page | 5-15 minutes per page |
| Accuracy (clean text) | 95-99% | 99%+ (if careful) |
| Accuracy (poor quality) | 70-90% | 95%+ (with effort) |
| Effort | Minimal (upload + review) | High (constant attention) |
| Best For | Batch processing, clean scans, screenshots | Critical documents, poor-quality sources, small amounts |
| Cost | Free (browser-based) | Time cost |
Verdict: OCR wins for batch processing and clean documents. Manual typing is better for critical documents where 100% accuracy is required, or for very poor-quality sources where OCR struggles.
Privacy & Security: Browser-Based OCR
Why processing images locally matters -- and how to verify a tool's privacy claims.
Privacy is critical when extracting text from sensitive documents like medical records, legal contracts, financial statements, or business confidential information. Not all OCR tools handle your data the same way.
Cloud-Based OCR
Your image is uploaded to a remote server for processing. The server may store, analyze, or share your data. Check the tool's privacy policy before uploading sensitive documents.
Browser-Based OCR
Processing happens entirely in your browser using WebAssembly or JavaScript. No uploads, no storage, complete privacy — the WASM engine reads pixels locally. AFFLIGO uses this approach.
Desktop OCR
Software installed on your computer processes files locally. Similar privacy to browser-based but requires installation. Examples: Tesseract, ABBYY FineReader.
Before using any OCR tool on sensitive documents, verify: (1) Does it process locally or upload to servers? (2) Is data stored after processing? (3) Who has access? When in doubt, use browser-based or desktop OCR that never uploads your files.
Use Cases: Business, Education, Personal
Practical applications of OCR across different domains.
Business
Receipts & Invoices: Extract amounts, dates, and vendor names for expense tracking. Business Cards: Digitize contact information instantly. Contracts: Make scanned agreements searchable.
Education
Research Papers: Extract text from printed papers for citing. Whiteboard Notes: Capture lecture content after class. Textbooks: Digitize passages for notes and study guides.
Personal
Handwritten Notes: Convert journal entries to digital text. Recipes: Extract family recipes from handwritten cards. Forms: Fill out PDF forms by extracting fields first.
Development
Error Logs: Extract error messages from screenshots for debugging. API Responses: Capture JSON or XML from screenshots. Documentation: Extract code snippets from images.
AFFLIGO OCR vs Other Tools
Phone-lens apps upload every receipt to a server — how an OCR that never sees a server compares.
| Feature | AFFLIGO | Google Drive | Tesseract | Online OCR Tools |
|---|---|---|---|---|
| Processing | Browser (local) | Cloud (Google servers) | Local (desktop) | Cloud (their servers) |
| Privacy | 100% private | Data on Google servers | 100% private | Data on their servers |
| Languages | 8 | 100+ | 100+ | Varies |
| Preprocessing | 4 modes | Automatic | Manual (config) | Varies |
| Installation | None (browser) | None (browser) | Required | None (browser) |
| Price | Free | Free | Free (open-source) | Free tier / paid |
| Export Formats | TXT, PDF | Google Docs | TXT, PDF, hOCR | Varies |
Common OCR Problems & Fixes
Troubleshooting guide for the most frequent OCR issues and their solutions.
| Problem | Likely Cause | Fix |
|---|---|---|
| Garbled output | Low resolution, poor contrast, wrong language | Resize to 300+ DPI, increase contrast, select correct language |
| Missing characters | Low contrast, compression artifacts, small font | Increase contrast, use PNG format, crop closer to text |
| "O" becomes "0" | Similar shapes confuse the engine | Manually review numbers and codes, use context to verify |
| Text is jumbled | Rotated or skewed input | Rotate image upright, use Aggressive preprocessing for deskew |
| Line breaks wrong | OCR grouped text boxes differently | Post-process in text editor, adjust line spacing manually |
| Tables lose structure | Basic OCR extracts text linearly | Use dedicated table extraction tools, export to Excel/CSV |
| Handwriting errors | Handwriting varies significantly | Retype key fields, use OCR as starting point only |
| Special characters wrong | Low image quality or wrong language model | Use a sharper source image; pick the correct language from the 8-language dropdown |
Frequently Asked Questions
Answers to the most common questions about OCR image-to-text conversion.
Related tools you might find useful:
Key Takeaways
- OCR extracts editable text from photos, scans, and screenshots using pattern recognition and neural networks
- When the output is wrong, work the defects in order: angle first, then resolution, then contrast, then noise. A language mismatch is the only cause no image fix can solve
- A 2-3 degree tilt is why one field can read perfectly while its neighbour is garbage — the baseline drifts within the line
- 300 DPI is the optimal resolution -- below 200 DPI causes significant accuracy drops, and a phone photo's DPI is fictional anyway
- PNG format is best for OCR due to lossless compression preserving text detail
- Choose the right preprocessing mode: Light for screenshots, Medium for average scans, Aggressive for poor quality — but never Aggressive on a clean image, where the forced threshold costs accuracy
- Browser-based OCR (like AFFLIGO) processes images locally -- no uploads, complete privacy
- Clean, high-resolution printed text achieves 95-99% accuracy; handwriting ranges from 50-92%
- Always review OCR output and fix similar-looking characters (O/0, l/1, rn/m)
- 8 languages supported -- pick the correct language before running for best accuracy on non-Latin scripts
I ran a clean screenshot and a tilted phone photo of a receipt: the screenshot extracted at near-100% accuracy, while the tilted receipt needed the Aggressive preprocessing mode to reach about 90%. Handwriting failed outright — print only, as documented.
Sources: Tesseract OCR docs, tesseract.js API docs, OCR accuracy behavior checked Aug 2026.
